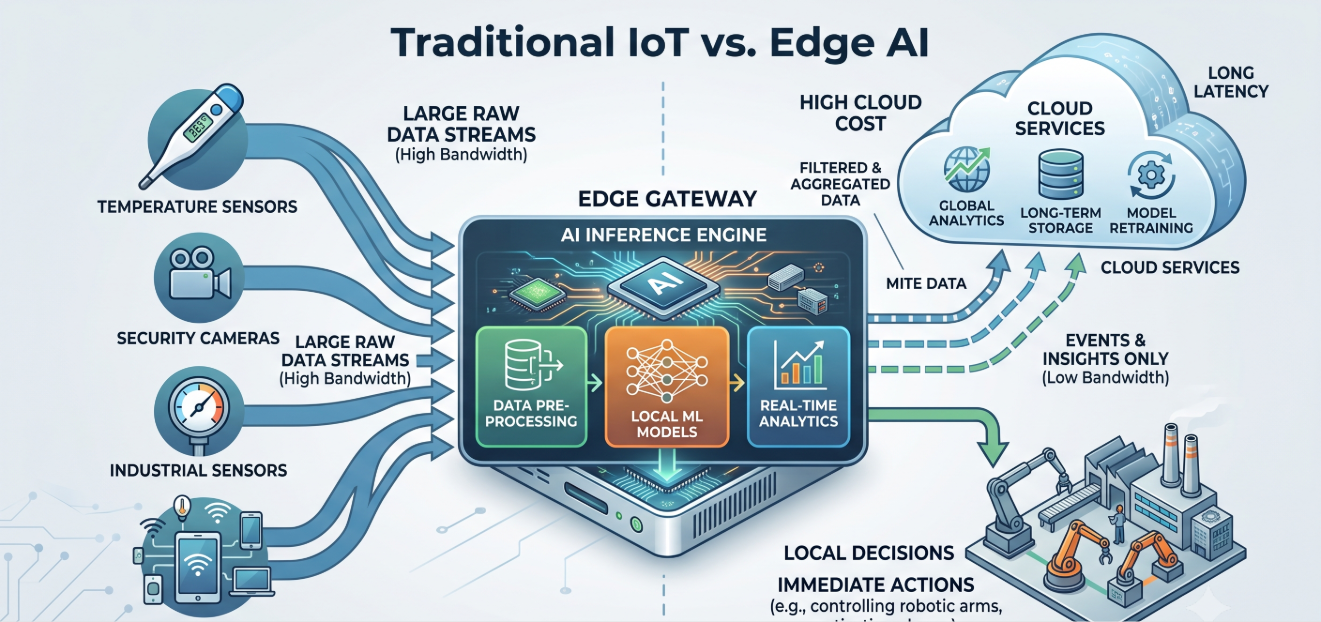

Edge AI in IoT Architecture: Where Intelligence Should Really Run

Traditional IoT systems collect data from sensors and send most of it to the cloud for storage, processing, and analysis. That model works well when connectivity is reliable and applications can tolerate network delays. It becomes less effective when devices need to react immediately, operate offline, process video or audio continuously, or minimize the amount of sensitive data leaving a site.
That is where Edge AI in IoT Architecture becomes important.
Instead of treating an IoT device purely as a source of data, Edge AI gives devices, gateways, and local computing systems the ability to analyze data and make decisions close to where events happen.
The result is not necessarily a cloud-free architecture. In most production systems, the better approach is hybrid: run time-sensitive intelligence locally while using the cloud for fleet management, model training, historical analytics, orchestration, and long-term storage.
What Is Edge AI in IoT Architecture?
Edge AI combines artificial intelligence with edge computing.
In a conventional cloud-centric IoT architecture, the flow may look like this:
Sensor → Network → Cloud → Processing → Application → Action
With Edge AI, part of that intelligence moves closer to the physical environment:
Sensor → Edge Device → AI Inference → Local Decision → Optional Cloud Synchronization
The edge device might be:
- an industrial computer
- an IoT gateway
- an embedded controller
- an AI camera
- a Raspberry Pi-class system
- an NVIDIA Jetson device
- a microcontroller
- a mobile device
- a local server
- a dedicated NPU or AI accelerator
The defining characteristic is not the hardware. It is where the decision happens.
If a camera detects whether a worker has entered a restricted area without sending every frame to a remote cloud service, AI inference is happening at the edge.
If a vibration sensor identifies abnormal machine behavior locally and only publishes an anomaly event, the intelligence has moved closer to the equipment.
AWS describes this model as performing inference directly on locally generated device data using cloud-trained models, allowing systems to combine local low-latency processing with cloud resources for training and management.
Why Edge AI Matters for IoT
IoT systems increasingly produce more information than organizations actually need to transmit.
Consider a camera producing a continuous video stream.
The business may not need the video itself. It may need answers such as:
- Is someone present?
- Has an object entered a restricted zone?
- Is a product defective?
- Is a safety helmet missing?
- Has a queue exceeded a threshold?
Edge AI changes the system from transporting raw data to transporting useful events.
Lower Latency
Sending sensor data across the internet, processing it in a cloud service, and waiting for a response creates network dependency.
For applications such as industrial control, robotics, safety monitoring, autonomous equipment, and machine vision, local inference can shorten the path between observation and action.
ONNX Runtime identifies reduced inference latency as one of the major benefits of deploying models directly on IoT and edge devices.
Lower Bandwidth Consumption
Suppose 100 cameras continuously upload video.
The architecture must support:
- network bandwidth
- cloud ingestion
- video processing
- storage
- data retention
- retrieval
With edge intelligence, cameras or local gateways can process video and send metadata instead.
Instead of uploading hours of footage, a device might publish:
person_detected=true
along with a timestamp, confidence score, device ID, and event snapshot.
Better Offline Operation
Edge systems can continue making decisions when connectivity becomes unreliable.
Microsoft describes Azure IoT Edge as supporting local analysis specifically to reduce cloud data transmission, respond quickly to events, and continue operating offline.
AWS Greengrass similarly supports local compute, messaging, data management, and inference while allowing devices to continue operating with intermittent connectivity.
Better Data Minimization
Edge processing can prevent unnecessary raw information from leaving the device or facility.
A system might process:
- video
- audio
- occupancy information
- equipment telemetry
- environmental measurements
locally and send only derived information to the cloud.
This does not automatically make an Edge AI system secure, but it can reduce unnecessary data movement and help support privacy-by-design architectures.
Lower Cloud Processing Costs
Cloud inference costs can increase as fleets grow.
Local inference shifts part of the compute workload toward the device.
The economic calculation therefore becomes a trade-off between:
- higher edge hardware cost
- lower network usage
- lower cloud inference volume
- lower cloud storage requirements
- local maintenance requirements
The cheapest architecture at 20 devices may not be the cheapest architecture at 20,000 devices.
Takeaway: Edge AI is most valuable when the cost or operational impact of moving data is greater than the cost of processing it locally.
If you are evaluating an IoT product architecture, defining exactly which decisions must happen locally and which can remain cloud-based often reveals the right edge strategy faster than selecting hardware first.
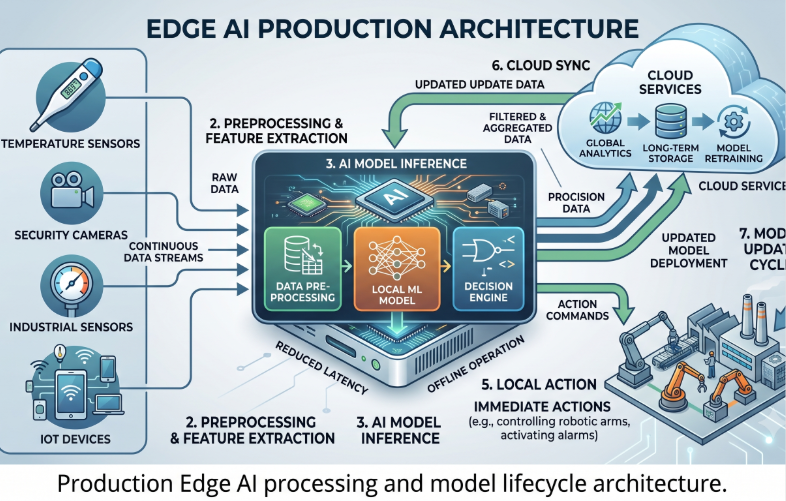
How Edge AI in IoT Architecture Works
A production Edge AI system usually contains several layers.
1. Sensor and Data Acquisition Layer
Everything begins with physical-world data.
Typical inputs include:
- cameras
- microphones
- temperature sensors
- humidity sensors
- vibration sensors
- pressure sensors
- current sensors
- air-quality sensors
- LiDAR
- radar
- accelerometers
- GPS
- machine PLC data
The quality of the AI system cannot exceed the quality of its input data.
Poor sensor placement, calibration problems, clock synchronization errors, or unreliable sampling can produce inaccurate predictions even when the machine-learning model itself performs well.
2. Edge Compute Layer
The edge compute layer receives the sensor data.
Its responsibilities may include:
- filtering
- normalization
- feature extraction
- AI inference
- event detection
- local storage
- protocol conversion
- rules
- actuator control
The required hardware depends heavily on the workload.
A temperature anomaly model may run on a small microcontroller.
A real-time multi-camera vision system may require a GPU or dedicated AI accelerator.
Generative AI requires substantially more memory and computation than many traditional classification models.
For example, NVIDIA lists the Jetson Orin Nano Super Developer Kit at up to 67 INT8 TOPS, 102 GB/s memory bandwidth, and configurable 7 W to 25 W operation for workloads including vision transformers, language models, robotics, and vision AI.
3. AI Inference Runtime
The model requires an inference engine capable of executing efficiently on the target hardware.
Common options include:
- ONNX Runtime
- TensorFlow Lite
- LiteRT
- NVIDIA TensorRT
- OpenVINO
- vendor-specific NPU runtimes
- custom embedded inference libraries
ONNX Runtime supports deployment across multiple IoT and edge architectures and highlights model size and hardware limitations as major considerations for on-device inference.
NVIDIA TensorRT optimizes models from frameworks including TensorFlow, PyTorch, and ONNX into optimized engines for NVIDIA GPUs across cloud, edge, and embedded environments.
4. Local Decision Layer
Inference alone does not make a useful IoT system.
The application must decide what to do with the prediction.
Consider predictive maintenance.
A model might return:
failure_probability = 0.84
The application still needs logic around that prediction.
Should it:
- create an alert?
- stop a machine?
- collect additional samples?
- upload diagnostic data?
- notify maintenance?
- wait until three consecutive anomalies appear?
Production architecture therefore separates prediction from operational action.
5. Connectivity and Messaging Layer
Edge systems still need communication.
Typical protocols include:
- MQTT
- HTTPS
- OPC UA
- Modbus
- BLE
- Wi-Fi
- Ethernet
- cellular
- LoRaWAN
MQTT is particularly common because publish-subscribe architectures work well for telemetry and asynchronous events.
Connectivity should be treated as unreliable by design.
Devices need strategies for:
- retry
- buffering
- store-and-forward
- duplicate messages
- timestamp handling
- reconnect behavior
- expired data
6. Cloud and Platform Layer
The cloud remains valuable even when inference happens locally.
Cloud services commonly handle:
- device provisioning
- fleet management
- long-term data storage
- dashboards
- historical analytics
- model training
- model registry
- configuration management
- OTA software updates
- model deployment
- monitoring
AWS Greengrass separates machine-learning functionality into model, runtime, and inference components that can be deployed to edge devices.
Microsoft's current IoT architecture guidance similarly treats sensing, networking, ingestion, processing, and application layers as distinct parts of a complete IoT solution. Azure IoT Operations provides an edge data plane running on Kubernetes-enabled environments.
7. Model Lifecycle Layer
This layer is frequently underestimated.
A model deployed today will probably not remain unchanged throughout the lifetime of an IoT product.
Production systems need ways to manage:
- model versions
- deployment groups
- rollback
- staged releases
- model metadata
- accuracy monitoring
- model drift
- retraining
- device compatibility
That makes MLOps part of IoT operations.
Edge AI Stack Options
There is no universal Edge AI stack.
The right combination depends on workload complexity, power availability, hardware cost, environmental requirements, latency, model size, and deployment scale.
Microcontrollers and TinyML
Use this approach when:
- power consumption must be extremely low
- models are small
- sensor inputs are relatively simple
- cost per device matters significantly
Common applications include vibration classification, wake-word detection, anomaly detection, and sensor pattern recognition.
The limitation is obvious: memory and compute resources are constrained.
ARM Linux Devices
Examples include Raspberry Pi-class computers and embedded Linux gateways.
They provide considerably more flexibility than microcontrollers and can run:
- Python
- containers
- MQTT brokers
- lightweight AI runtimes
- local databases
- application services
They are useful for gateways, smaller vision workloads, industrial data processing, and prototypes.
NVIDIA Jetson
Jetson systems are widely used for workloads involving:
- computer vision
- robotics
- multimodal AI
- video analytics
- generative AI
- autonomous systems
TensorRT provides NVIDIA-specific inference optimization, including lower-precision inference options.
ONNX Runtime
ONNX is attractive when portability matters.
A team can train models using different frameworks and export compatible models into an intermediate format that can run across multiple hardware platforms.
This can reduce dependence on one machine-learning training ecosystem.
AWS IoT Greengrass
Greengrass is appropriate when an architecture already depends heavily on AWS services and needs:
- local workloads
- fleet deployment
- messaging
- ML inference
- cloud-edge integration
The platform supports custom runtimes as well as AWS-provided ML components.
Azure IoT Operations
Azure IoT Operations is designed around edge-based workloads operating on Arc-enabled Kubernetes infrastructure and is particularly relevant to industrial systems and organizations already using the Microsoft ecosystem.
LiteRT and On-Device Generative AI
Generative AI is increasingly entering the edge architecture discussion.
Google's LiteRT-LM supports local LLM execution across Android, iOS, desktop, web, and IoT platforms including Raspberry Pi, with GPU and NPU acceleration where available.
This makes hybrid designs possible where smaller models operate locally while more computationally demanding requests are escalated to larger cloud models.
Best Practices for Edge AI Architecture
Start With the Decision, Not the Model
Do not begin with:
Which AI model should we use?
Begin with:
What decision must the system make, and how quickly must it make it?
Then determine:
- required inputs
- acceptable latency
- accuracy threshold
- fallback behavior
- connectivity dependency
- output requirements
Measure End-to-End Latency
Model inference time is only one component.
Total latency may include:
- sensor capture
- preprocessing
- model inference
- post-processing
- decision logic
- network communication
- actuator response
A model that runs in 20 milliseconds does not produce a 20-millisecond system if preprocessing requires another 100 milliseconds.
Optimize Models for Target Hardware
A model that performs well on a cloud GPU may be unsuitable for an embedded device.
Common optimization techniques include:
- quantization
- pruning
- distillation
- hardware-specific compilation
- reduced input dimensions
- smaller architectures
- batching where latency permits
ONNX Runtime explicitly notes that edge deployment requires models to fit the memory and compute limitations of the target device.
Design for Connectivity Failure
Ask:
- What happens if connectivity disappears for ten minutes?
- What if it disappears for three days?
- How much data can the device buffer?
- Which functions continue locally?
- Which operations require the cloud?
- How are timestamps reconciled after reconnection?
Offline behavior should be part of the initial architecture rather than added later.
Keep Raw Data Local Where Possible
Instead of transmitting everything, send:
- events
- aggregates
- anomalies
- summaries
- selected samples
Raw data can still be uploaded when required for diagnostics, audits, or model improvement.
Separate AI From Safety Logic
AI predictions are probabilistic.
Safety-critical actions should therefore include deterministic controls, thresholds, validation, interlocks, or human review where appropriate.
Plan OTA and Model Updates From Day One
A production Edge AI product needs both software updates and model updates.
NIST's IoT cybersecurity baseline specifically identifies secure software update capabilities, including authenticating updates and restricting update actions to authorized entities.
Monitor the AI, Not Just the Device
Traditional device health might track:
- CPU
- memory
- temperature
- disk space
- connectivity
Edge AI adds new health metrics:
- inference latency
- confidence distribution
- failed inference count
- model version
- input quality
- drift indicators
- accelerator utilization
A device can be online while its AI is performing badly.
Common Edge AI Pitfalls
Before deployment, verify that the system addresses the following.
- The model has been tested on production hardware.
- Latency is measured end to end.
- Offline behavior is defined.
- Model updates support rollback.
- Device and model versions are identifiable.
- Sensor quality is monitored.
- Raw and derived data have clear retention policies.
- Local storage limits are known.
- Connectivity retry logic is tested.
- Failed inference behavior is defined.
- AI confidence thresholds are configurable.
- Devices can be diagnosed remotely.
- Hardware thermals are tested under sustained load.
- Power consumption is measured in real operating conditions.
- Security is included in provisioning and OTA design.
A proof of concept usually proves that inference works.
A production architecture must prove that the entire lifecycle works.
Performance, Cost, and Security Considerations
Performance
The most important metrics depend on the application.
Common measurements include:
- inference latency
- frames per second
- throughput
- memory consumption
- CPU/GPU/NPU utilization
- power consumption
- startup time
- thermal behavior
A useful metric is often performance per watt, not raw compute performance.
An accelerator capable of impressive benchmark results may be unsuitable if the device is battery powered or passively cooled.
Cost
Edge AI introduces different cost categories from cloud AI.
Budget for:
- processor or accelerator
- additional RAM
- storage
- thermal management
- enclosure changes
- local software
- monitoring
- device management
- OTA infrastructure
- engineering support
But these costs can replace or reduce:
- cloud inference
- network bandwidth
- data ingestion
- storage
- centralized compute
The right comparison is therefore total lifecycle cost, not edge hardware price versus a single cloud API request.
If an IoT deployment is approaching production scale, modeling bandwidth, cloud inference, fleet-management overhead, field support, and edge hardware together usually provides a much more realistic architecture decision.
Security
Edge AI expands the attack surface because devices now contain:
- models
- credentials
- data
- application logic
- local APIs
- update mechanisms
Security controls should include:
- unique device identities
- encrypted communications
- secure boot where available
- signed software
- authenticated model updates
- restricted interfaces
- protected credentials
- least-privilege access
- device health monitoring
- rollback protection
- vulnerability management
NIST's IoT cybersecurity capabilities include device identification, configuration, data protection, logical access control, secure software updates, cybersecurity-state awareness, and device security.
NIST also updated its foundational IoT manufacturer guidance in April 2026, emphasizing that cybersecurity needs to be addressed across product development and lifecycle support rather than added after deployment.
Real-World Edge AI Use Cases
Predictive Maintenance
A vibration sensor collects machine signatures.
Instead of streaming every measurement to the cloud, a local model identifies changes associated with bearing wear or imbalance.
Normal readings remain local.
Potential anomalies trigger:
- an alert
- a diagnostic data upload
- maintenance workflow creation
Industrial Visual Inspection
A production camera captures each product.
A local vision model classifies defects before the item leaves the inspection station.
The system may send only:
- defect class
- confidence score
- timestamp
- production batch
- selected image
This avoids continuously uploading high-resolution images.
Indoor Environment Monitoring
Environmental sensors may measure:
- CO₂
- PM2.5
- temperature
- humidity
- VOCs
- occupancy
Edge intelligence can combine environmental conditions with occupancy and time to determine whether a location needs ventilation or investigation.
Instead of simply displaying sensor readings, the device or gateway can identify persistent patterns and trigger operational actions.
Retail Analytics
Local vision processing can estimate:
- footfall
- queue length
- occupancy
- dwell time
Derived statistics can be transmitted without centrally storing continuous video.
Robotics
Robots need fast perception and decision loops.
Sending every camera frame to a remote cloud service is not practical for many navigation or manipulation tasks.
Modern edge platforms are increasingly capable of running vision-language models and other generative AI workloads locally. NVIDIA, for example, documents current Jetson platforms running compact LLMs and multimodal models directly at the edge.
Edge AI vs. Cloud AI
Edge AI does not replace cloud AI.
They solve different parts of the problem.
Use Edge AI When
Choose local inference when the system requires:
- very low latency
- offline operation
- reduced bandwidth
- local privacy
- immediate control
- continuous sensor processing
Use Cloud AI When
Cloud inference may be better when:
- models are extremely large
- workloads are intermittent
- centralized compute is more economical
- edge hardware is highly constrained
- global data aggregation is required
- frequent model changes are expected
Use Hybrid Architecture When
For many IoT products, hybrid architecture is the strongest option.
A hybrid workflow might be:
Sensor → Edge filtering → Edge AI → Local action → Event to cloud → Fleet analytics → Model retraining → Updated model back to edge
The cloud handles fleet-scale intelligence.
The edge handles immediate intelligence.
Edge AI vs. Edge Computing
These terms are related but not identical.
Edge computing means performing computation near the source of data.
That computation may involve simple:
- filtering
- rules
- aggregation
- protocol translation
- local storage
Edge AI specifically adds machine-learning inference or AI-driven decision making.
Every Edge AI architecture uses edge computing.
Not every edge-computing system uses AI.
Edge AI vs. TinyML
TinyML is a narrower category.
TinyML generally refers to machine-learning models running on extremely resource-constrained hardware, particularly microcontrollers.
Edge AI includes TinyML but also covers much more capable platforms such as:
- embedded Linux computers
- GPUs
- NPUs
- industrial edge servers
- AI cameras
A TinyML model might detect an abnormal vibration pattern using milliwatts.
An Edge AI server might analyze 20 video feeds simultaneously.
Both perform AI close to the data source, but their hardware and application constraints are very different.
Generative AI at the Edge
Generative AI adds another layer to Edge AI architecture.
Traditional edge models often produce structured outputs such as:
- class A
- class B
- anomaly detected
- object located
- probability 0.82
Generative AI allows devices to create more flexible outputs.
A factory system could combine visual information, maintenance manuals, and equipment telemetry and answer:
Why might this machine be behaving abnormally?
A smart camera could summarize activity rather than simply count objects.
A robot could interpret natural-language instructions.
Local generative AI is becoming more practical as smaller models and optimized inference runtimes improve.
Google's LiteRT-LM now supports on-device language models across multiple platforms, including IoT hardware.
NVIDIA's current edge documentation also supports LLM and vision-language inference across Jetson-class hardware, including models specifically optimized for constrained edge environments.
However, the architecture challenge remains unchanged:
Do not run a model at the edge simply because it can run there.
Run it locally when latency, privacy, connectivity, cost, or operational autonomy makes the local decision valuable.
FAQs
What is Edge AI in IoT?
Edge AI in IoT means running machine-learning inference close to IoT sensors or devices instead of sending all raw data to a centralized cloud service. The AI may operate directly on a device, gateway, industrial PC, or local edge server.
How does Edge AI work with IoT devices?
IoT sensors collect data and send it to a nearby computing system. An AI model analyzes the data locally, generates a prediction, and triggers an action or event. Only selected results may then be synchronized with the cloud.
What are the main benefits of Edge AI?
The primary benefits are lower latency, reduced bandwidth usage, better offline operation, greater data minimization, faster local decision making, and potentially lower cloud-processing costs.
Can Edge AI work without internet connectivity?
Yes. Edge AI can continue performing local inference without an internet connection if the required model, software, and decision logic are stored locally. Cloud-dependent functions such as model updates or centralized analytics may be delayed until connectivity returns.
Is Edge AI more secure than cloud AI?
Not automatically.
Keeping sensitive data local can reduce unnecessary transmission, but edge devices create their own security requirements. Devices still need secure identities, encrypted communication, access controls, trusted updates, credential protection, monitoring, and lifecycle security.
What hardware is needed for Edge AI?
Hardware depends on the workload. Tiny models can run on microcontrollers, while computer vision may require an NPU or GPU. Generative AI and multimodal applications may require devices with considerably more memory and accelerated compute.
What is the difference between Edge AI and TinyML?
TinyML usually refers to machine learning running on highly resource-constrained microcontrollers. Edge AI is broader and includes everything from microcontrollers to embedded computers, gateways, GPU systems, and industrial edge servers.
Can generative AI run on IoT edge devices?
Yes, increasingly so.
Compact language models, multimodal models, quantization, and optimized runtimes are making local generative AI practical on increasingly capable edge hardware. Model size, memory, power consumption, and latency remain important constraints.
Does Edge AI eliminate the need for the cloud?
Usually not.
Production architectures often use the cloud for model training, fleet management, software deployment, analytics, historical storage, dashboards, and cross-device intelligence while using the edge for real-time decisions.
What is the biggest challenge in Edge AI deployment?
The hardest challenge is rarely getting a model to run once.
The bigger challenge is operating thousands of devices reliably while managing hardware resources, connectivity, OTA updates, model versions, security, monitoring, failures, and model performance over the product lifecycle.
The real value of Edge AI is not putting AI on a device. It is putting the right intelligence close enough to the problem to make a useful decision at the right time.

Conclusion
Edge AI is changing IoT architecture from a simple data-collection model into a distributed intelligence model.
But moving every AI workload to the edge is not the goal. The better architecture decides what must happen locally, what can wait for the cloud, and how devices, models, connectivity, security, and fleet operations work together.
For time-sensitive decisions, privacy-sensitive data, bandwidth-heavy workloads, and environments with unreliable connectivity, local intelligence can create significant operational value. The cloud still plays an important role in model training, analytics, fleet management, updates, and long-term learning.
The most effective Edge AI architecture is therefore usually hybrid.
Start with the operational decision. Define the latency, connectivity, privacy, compute, and lifecycle requirements. Then choose where the intelligence should run.
That decision will shape almost everything that follows.
Planning an IoT product that needs AI at the edge?
I help teams evaluate device, edge, and cloud architecture before hardware and platform decisions become expensive to change.
Get in touch to discuss your Edge AI or connected-product architecture.


