
Frontier Models vs Small Language Models: Stop Paying for Intelligence You Don’t Need

The instinct behind many generative AI projects is understandable: choose the most capable model available.
It also creates an expensive architectural mistake.
A company may use a frontier model to classify support tickets, extract fields from invoices, summarize sensor alerts, generate product tags, or convert text into structured JSON. The model can certainly perform those tasks. The real question is whether that level of intelligence was necessary.
Increasingly, it is not.
Small language models are becoming capable enough to handle a growing percentage of production workloads while offering lower cost, faster responses, easier deployment, and potentially greater control.
The right question is therefore no longer:
Which AI model is the smartest?
It is:
What is the smallest model that can reliably complete this particular job?
That distinction can fundamentally change the economics of enterprise AI.
What Are Frontier Models?
Frontier models are among the most capable general-purpose AI models available at a particular point in time.
They are typically optimized for difficult tasks involving combinations of:
- complex reasoning
- coding
- long-context analysis
- multimodal understanding
- planning
- tool use
- ambiguous instructions
- scientific or mathematical reasoning
- multi-step workflows
Their biggest advantage is versatility.
You can give a capable frontier model an unfamiliar problem and reasonably expect it to determine how to approach it.
That flexibility matters when your workload is unpredictable.
A research assistant analyzing several technical documents, for example, may encounter questions ranging from simple extraction to complex reasoning across conflicting sources. A frontier model gives the system more room to handle those variations.
But that capability carries a cost.
Frontier models generally require more compute, may introduce more latency, and can cost considerably more per request than smaller alternatives.
Current API pricing illustrates the difference clearly. OpenAI lists GPT-5.4 at $2.50 per million input tokens and $15 per million output tokens, while GPT-5.4 mini is listed at $0.75 and $4.50 respectively. GPT-5.4 nano is priced lower again at $0.20 per million input tokens and $1.25 per million output tokens. Pricing changes over time, but the architectural lesson remains: model selection can create a substantial cost difference at scale.
Using a frontier model is therefore valuable when the problem actually requires frontier-level capability.
Using one for every problem is another matter.
What Are Small Language Models?
A small language model, or SLM, is a language model designed to deliver useful AI capabilities with substantially fewer parameters or lower computational requirements than very large general-purpose models.
There is no universal parameter count that officially separates an SLM from an LLM.
The useful distinction is operational.
Small models are generally optimized for efficiency.
They can be particularly attractive when workloads are:
- repetitive
- narrowly defined
- high volume
- latency sensitive
- privacy sensitive
- executed on limited hardware
- easy to evaluate objectively
Examples include:
- document classification
- entity extraction
- sentiment detection
- routing requests
- structured data generation
- simple summarization
- FAQ responses
- command interpretation
- sensor-event explanation
- basic coding assistance
Smaller does not automatically mean primitive.
Stanford's 2025 AI Index highlighted how rapidly smaller models have improved. In 2022, the smallest model exceeding 60% on the MMLU benchmark had 540 billion parameters. By 2024, Microsoft's 3.8-billion-parameter Phi-3-mini crossed the same threshold, representing roughly a 142-fold reduction in model size for that level of benchmark performance.
Microsoft's later Phi-4 work also showed that a 14-billion-parameter model could achieve strong reasoning performance relative to its size, emphasizing the importance of data quality and training methods rather than model scale alone.
The trend is important.
Capability is no longer increasing only by making models bigger.
How Frontier and Small Models Fit Into an AI Architecture
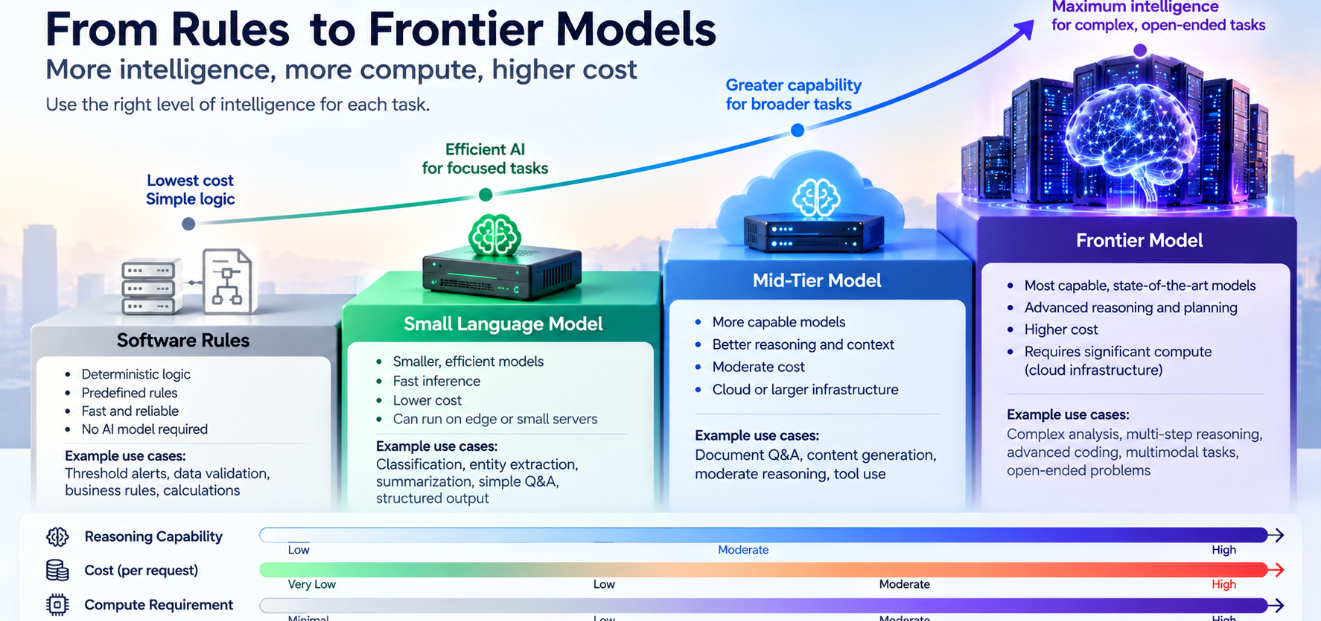
Instead of thinking about frontier models and small language models as competitors, think about them as different compute tiers.
Imagine an enterprise AI system receiving 100,000 requests.
Perhaps:
- 35,000 requests involve classification.
- 25,000 involve structured data extraction.
- 20,000 involve straightforward summaries.
- 10,000 involve document Q&A.
- 7,000 require moderate reasoning.
- 3,000 require complex multi-step analysis.
Sending all 100,000 requests to your most powerful model is simple architecturally.
It may also be unnecessarily expensive.
A better architecture introduces an AI model router.
The workflow becomes:
Request → Task Classification → Model Selection → Execution → Validation → Escalation if Required
A lightweight model handles predictable work.
A stronger model handles moderately difficult tasks.
The frontier model receives only the tasks that genuinely require advanced reasoning.
This is sometimes called model routing, model cascading, or tiered inference.
The goal is not to minimize AI cost at any price.
The goal is to minimize:
Cost per successful outcome.
If a small model completes a task correctly 99% of the time, routing that workload to a frontier model simply because the frontier model scores slightly better may not create meaningful business value.
But if a task involves complex legal reasoning, difficult engineering analysis, or an autonomous agent making high-impact decisions, the additional intelligence may be worth considerably more than the additional inference cost.
If your AI workload has grown beyond experimentation, evaluating which requests actually need frontier reasoning can uncover significant optimization opportunities.
Why Small Models Are Becoming More Important
Three trends are changing the economics.
AI capability is becoming cheaper
Stanford's AI Index found that the cost of querying a model achieving roughly GPT-3.5-level MMLU performance fell from about $20 per million tokens in November 2022 to $0.07 by October 2024.
That represents a reduction of more than 280 times in approximately 18 months.
This means yesterday's expensive capability can become tomorrow's commodity capability.
Smaller models are becoming more capable
Better training data, distillation, quantization, fine-tuning, model architecture, and synthetic data are allowing smaller models to perform tasks that previously required much larger systems.
Research surveying small language models has found that models in roughly the 1B to 8B parameter range can deliver competitive performance for certain tasks while improving efficiency and deployment flexibility.
AI is moving closer to the edge
Not every AI interaction needs to travel to a massive cloud model.
Google's Gemma family, for example, includes models designed to operate across environments ranging from cloud infrastructure to laptops and resource-constrained systems. Google specifically notes that smaller model sizes make local deployment practical on devices such as laptops and desktops.
That matters particularly for IoT, industrial systems, mobile applications, healthcare devices, and environments with intermittent connectivity.
Tools and Stack Options
There is no single correct AI stack.
The architecture depends on where inference happens and how specialized the workload is.
Hosted frontier models
Hosted frontier APIs are a strong fit when maximum intelligence matters more than complete infrastructure control.
They work well for:
- research assistants
- complex coding
- advanced document analysis
- multimodal reasoning
- AI agents
- ambiguous workflows
The main advantages are rapid adoption and access to highly capable models.
The trade-offs include usage-based cost, dependence on external infrastructure, and data-governance considerations.
Hosted smaller models
Many AI platforms now provide mini, nano, flash, or lightweight model tiers.
These can be ideal for high-volume workloads such as:
- extraction
- classification
- summarization
- routing
- structured output
- straightforward question answering
They preserve the convenience of API-based inference while lowering operating cost.
Open-weight models
Models such as Gemma and other open-weight families allow organizations to run inference on their own cloud infrastructure or local hardware.
This provides greater control over:
- deployment
- optimization
- infrastructure
- data movement
- model customization
However, infrastructure responsibility moves to your team.
Running a model yourself is not automatically cheaper than using an API. GPU utilization, deployment engineering, observability, scaling, model updates, and operations all contribute to total cost.
Edge and on-device models
For certain workloads, models can run directly on gateways, PCs, smartphones, or embedded computing platforms.
This can reduce:
- network dependency
- cloud round trips
- latency
- data transfer
It can also keep sensitive information closer to the source.
The trade-off is tighter limits on compute, memory, model size, and update management.
Best Practices for Choosing an AI Model
Model selection should begin with the workload, not the model leaderboard.
1. Define the task narrowly
Do not benchmark a model against a vague requirement such as:
"Answer customer questions."
Define the actual tasks.
For example:
- retrieve account information
- explain product features
- classify the intent
- summarize a support history
- recommend troubleshooting steps
- escalate unusual cases
Different parts of the same workflow may require different intelligence levels.
2. Create a representative evaluation set
Build examples from real usage.
Include:
- normal cases
- difficult cases
- unusual inputs
- incomplete information
- adversarial inputs
- edge cases
Evaluate models against the work they will actually perform.
3. Start smaller than you think
Test a capable small model first.
If it meets your quality threshold, you have already solved the problem.
If it fails, move upward.
This creates a rational escalation path rather than beginning with the most expensive option.
4. Measure business accuracy
Traditional AI benchmarks are useful, but production success should be measured using metrics that matter to the application.
Examples include:
- extraction accuracy
- successful task completion
- hallucination rate
- escalation rate
- response latency
- structured-output validity
- cost per completed workflow
5. Route difficult cases upward
Small models do not have to solve everything.
If confidence is low or validation fails, route the request to a stronger model.
The system becomes:
Small model first → Validate → Escalate when necessary
That architecture can maintain quality without paying frontier-model prices for every request.
Common Pitfalls
Choosing models from benchmark rankings alone
Benchmarks measure generalized capabilities.
Your production workload may be much narrower.
A model ranked lower overall may outperform a frontier model economically on your specific task.
Optimizing only for token price
Cheap tokens do not necessarily mean a cheap workflow.
A model that frequently fails can create:
- retries
- human reviews
- escalations
- longer prompts
- larger outputs
Evaluate the entire transaction.
Using one model for everything
AI applications often begin this way because it simplifies development.
The problem appears later when usage scales.
Architecture that seemed inexpensive at 5,000 calls may become costly at five million.
Fine-tuning too early
Fine-tuning can improve specialized performance, but it should not be the first solution to every model problem.
Better prompting, retrieval, structured context, deterministic logic, and workflow redesign may solve the problem with less operational complexity.
Ignoring deterministic software
Not every problem requires AI.
If a business rule can be expressed reliably as:
if temperature > threshold, trigger alert
use software logic.
Calling a language model for deterministic calculations can increase both cost and unpredictability.
Performance, Cost and Security Considerations
Model selection affects considerably more than intelligence.
Cost
Inference cost becomes especially important at volume.
Imagine a workload with millions of daily requests. A difference of a fraction of a cent per request can become a meaningful annual infrastructure expense.
Look beyond token pricing and calculate:
Infrastructure + inference + retries + validation + human review + operations
That is your real AI cost.
Latency
Smaller models can often respond faster because they require less computation.
For interactive systems, the difference between a near-immediate response and several seconds of waiting can materially affect usability.
Privacy
Local or self-hosted models can reduce the amount of sensitive information leaving controlled infrastructure.
However, local deployment does not automatically make an application secure.
Teams still need:
- access control
- encryption
- logging
- secure model distribution
- input validation
- data retention policies
- patching
- monitoring
Reliability
Frontier intelligence cannot replace application engineering.
Production AI still requires guardrails around the model.
Use validation where results can be checked deterministically.
For example, if the model must produce JSON containing five specific fields, software should verify the output before accepting it.
The production question should therefore be:
What combination of model intelligence and software controls gives us the required reliability at an acceptable cost?
That is a better engineering question than simply asking which model has the highest benchmark score.
If your application is already using generative AI in production, benchmarking a smaller model against a representative workload is often one of the simplest ways to test whether your current architecture is overprovisioned.
Real-World Example: Industrial IoT Alert Processing
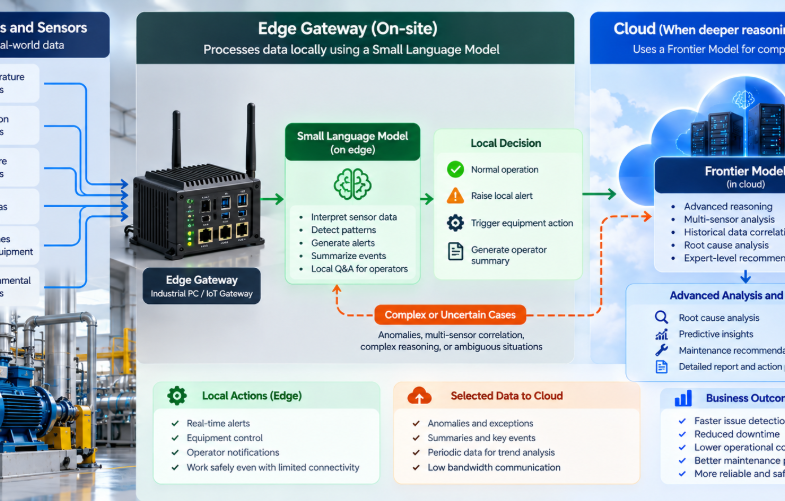
Consider an industrial IoT platform monitoring thousands of connected devices.
Sensors continuously transmit:
- temperature
- vibration
- pressure
- device health
- network status
- battery level
- diagnostic codes
The platform generates thousands of events.
Does every event need a frontier AI model?
Probably not.
Stage 1: Deterministic processing
Software identifies obvious conditions:
- device offline
- temperature threshold exceeded
- missing telemetry
- low battery
- firmware mismatch
No language model is needed.
Stage 2: Small-model interpretation
A small language model converts technical signals into operator-friendly explanations:
"Motor 18 has reported increasing vibration for four consecutive measurement windows."
It might also:
- classify alert severity
- summarize event history
- extract relevant maintenance records
- generate technician notes
These are well-defined tasks.
Stage 3: Advanced reasoning
Now imagine vibration, temperature, maintenance history, environmental conditions, and several diagnostic codes show conflicting signals.
The system could escalate that case to a frontier model.
The frontier model receives the richer context and performs deeper reasoning.
Instead of:
Every event → Frontier model
the architecture becomes:
Sensor → Rules → Small model → Frontier model only when needed
That is a more efficient use of intelligence.
Frontier Models vs Small Language Models: Where Each Wins
Choose a frontier model when:
- the task is ambiguous
- multiple reasoning steps are required
- prompts vary dramatically
- advanced coding is required
- the model must plan actions
- several tools must be coordinated
- multimodal reasoning matters
- failure from inadequate reasoning is expensive
- there is no easy way to define the workflow beforehand
Choose a small language model when:
- the task is narrow
- outputs follow predictable patterns
- volume is high
- latency matters
- cost matters
- local deployment is valuable
- privacy requires more infrastructure control
- output can be validated
- edge deployment is desirable
Use both when:
Most production AI systems will eventually fit here.
Use small models for predictable work and frontier models for exceptions.
This is similar to human organizations.
You do not ask your most senior engineer to perform every repetitive operational task merely because they are capable of doing it.
You reserve scarce expertise for work where that expertise changes the result.
AI infrastructure should increasingly work the same way.
The Emerging Pattern: AI Model Cascades
A mature generative AI architecture may involve several layers of intelligence.
A request arrives.
A lightweight classifier identifies the workload.
Simple tasks go to a small model.
Moderate reasoning goes to a mid-tier model.
Complex cases go to a frontier model.
Validation checks the output.
Failures escalate.
Over time, telemetry shows which workloads can safely move downward to cheaper models.
This creates continuous AI cost optimization.
The architecture could look like:
User or Device
↓
API Gateway
↓
AI Router
↓
Small Model | Mid-Tier Model | Frontier Model
↓
Validation Layer
↓
Application or Workflow
The key component is not any individual model.
It is the routing logic around them.
That makes the architecture less dependent on whichever model happens to lead benchmarks this month.
How to Find the Smallest Model That Works
A practical evaluation can follow six steps.
Step 1: Pick one production workflow
Avoid testing vague "general intelligence."
Choose something measurable such as invoice extraction, ticket classification, or alert summarization.
Step 2: Collect representative examples
A useful test set should include easy, normal, difficult, and failure cases.
Step 3: Establish acceptance criteria
Define what success means before testing.
For example:
- at least 98% classification accuracy
- less than 1% invalid JSON
- under two seconds median latency
- below a target cost per 1,000 transactions
Step 4: Test smaller models first
Measure the lowest-cost model against the acceptance criteria.
Step 5: Escalate only when required
If the model cannot meet the target, test the next capability tier.
Step 6: Monitor production drift
Real workloads change.
Continue measuring quality, latency, escalation frequency, and cost after deployment.
FAQs
What is a frontier AI model?
A frontier AI model is a highly capable general-purpose model near the leading edge of current AI performance. These models are particularly useful for complex reasoning, coding, multimodal understanding, planning, and unfamiliar problems.
What is a small language model?
A small language model is a more computationally efficient language model designed to perform useful language or reasoning tasks with fewer resources than very large models. SLMs are especially useful for focused, high-volume, or local workloads.
Are small language models cheaper?
They often are, particularly when consumed through lower-cost API tiers or deployed efficiently on owned infrastructure. However, organizations should calculate total cost rather than token price alone.
Can small language models replace frontier models?
For specific tasks, yes.
For all tasks, no.
Classification, extraction, routing, summarization, and structured generation may perform very well on smaller models. Highly complex reasoning may still benefit materially from frontier models.
When should I use a small language model?
Use one when the workload is predictable, measurable, repetitive, latency sensitive, high volume, privacy sensitive, or suitable for local execution.
Are SLMs suitable for enterprise AI?
Yes. Their suitability depends on the application rather than company size. A narrowly defined enterprise workflow can be an excellent candidate for a small model.
Can small language models run on edge devices?
Some can.
Hardware requirements vary substantially, but advances in quantization and smaller model architectures increasingly allow AI inference on PCs, gateways, smartphones, and other edge-computing systems.
Are smaller models more secure?
Not automatically.
Running a smaller model locally can reduce external data transfer, but application security still depends on access controls, encryption, model security, infrastructure configuration, monitoring, and data-governance practices.
What is AI model routing?
AI model routing is the practice of selecting different models based on the complexity, cost, latency, or risk of each request.
Simple requests may go to inexpensive models while difficult cases automatically escalate to more capable ones.
How should companies compare AI models?
Test models against representative production tasks and measure quality, latency, reliability, security requirements, operational complexity, and cost per successful task.
The best AI model is not the smartest model available. It is the smallest model that reliably gets the job done.

Conclusion
The future of enterprise AI is unlikely to be built around one model handling everything.
Predictable, high-volume tasks can often be handled efficiently by small language models. Complex reasoning, unfamiliar problems, and high-impact decisions may still justify frontier models. The real opportunity is knowing where each belongs.
Instead of asking, “What is the most powerful model we can use?”, engineering teams should ask, “What is the least expensive level of intelligence that can reliably complete this task?”
That shift changes AI economics. It reduces unnecessary inference costs, improves latency, opens opportunities for edge and local deployment, and reserves expensive reasoning for the workloads where it actually creates value.
The strongest AI architectures will increasingly combine deterministic software, small models, model routing, validation, and frontier models into one intelligent workflow.
Are you paying for more AI intelligence than your application actually needs?
Infolitz helps teams evaluate Generative AI, edge AI, IoT, and enterprise AI workloads to determine where small models, frontier models, or a hybrid architecture make the most technical and economic sense.
Talk to Infolitz about designing the right AI architecture for your workload.


