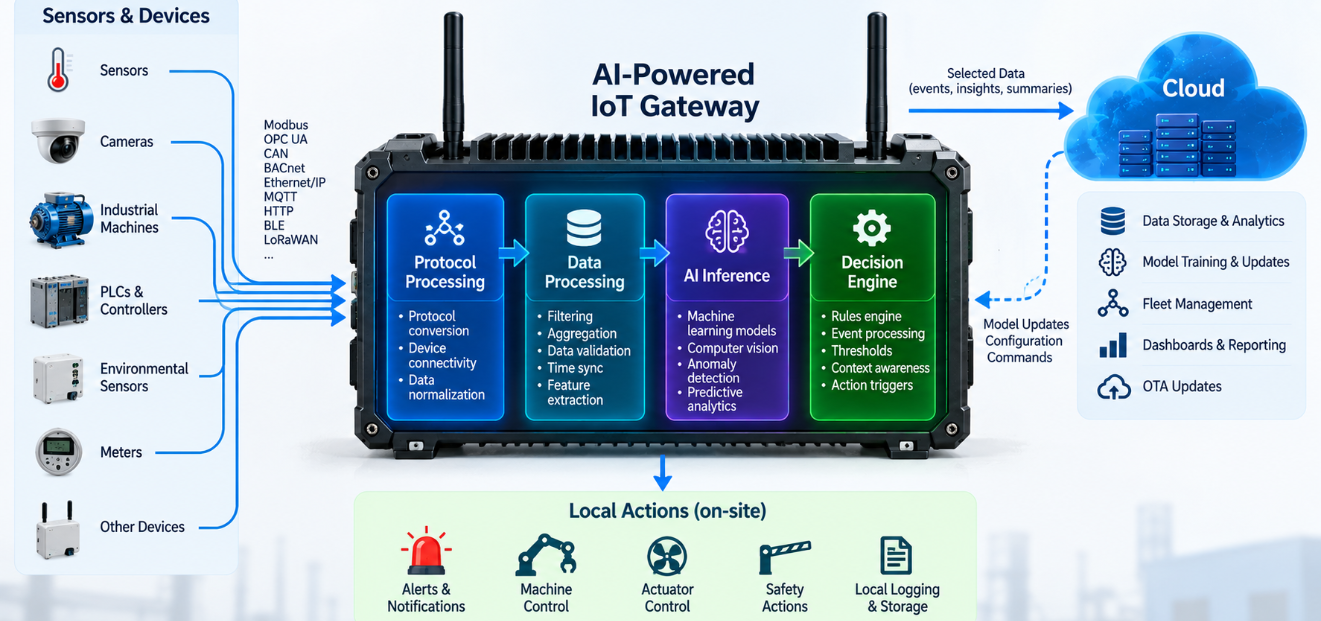

The Intelligent Gateway: Why IoT Gateways Are Becoming AI Computers

For years, an IoT gateway had a fairly simple job.
It collected data from devices, translated protocols, applied basic rules, and sent information to the cloud.
That architecture worked when connectivity was reliable, data volumes were manageable, and most intelligence lived in centralized applications.
AI is changing that model.
Modern AI-powered IoT gateways can now run machine learning inference, computer vision, anomaly detection, filtering, automation logic, and even some generative AI workloads directly beside the machines producing the data.
Instead of asking:
“How do we send this data to the cloud?”
IoT architects increasingly ask:
“Which decisions should happen locally before the cloud is involved?”
That shift is turning the gateway into something closer to a small AI computer.
This article explains why that is happening, what an intelligent IoT gateway looks like, how the architecture works, and where edge AI genuinely adds value.
What Is an AI-Powered IoT Gateway?
An AI-powered IoT gateway is an edge computing device that connects sensors, machines, controllers, cameras, or other IoT devices while also running local AI or machine learning workloads.
A traditional gateway may perform functions such as:
- Modbus-to-MQTT conversion
- BLE-to-IP connectivity
- Device authentication
- Data aggregation
- Message buffering
- Basic filtering
- Cloud connectivity
An AI gateway adds another layer:
- Machine learning inference
- Computer vision
- Predictive analytics
- Anomaly detection
- Pattern recognition
- Intelligent event filtering
- Local decision-making
- Automated actions
The important distinction is that raw data no longer has to leave the site before it becomes useful information.
For example, imagine an industrial camera producing 30 video frames every second.
A traditional architecture may stream video toward a centralized server.
An edge AI gateway could instead analyze the video locally, detect a safety violation, trigger an alarm, and send only the event metadata to the cloud.
That is a very different architecture.
Why IoT Gateways Are Becoming AI Computers
Several technology trends are converging.
More compute is available at the edge
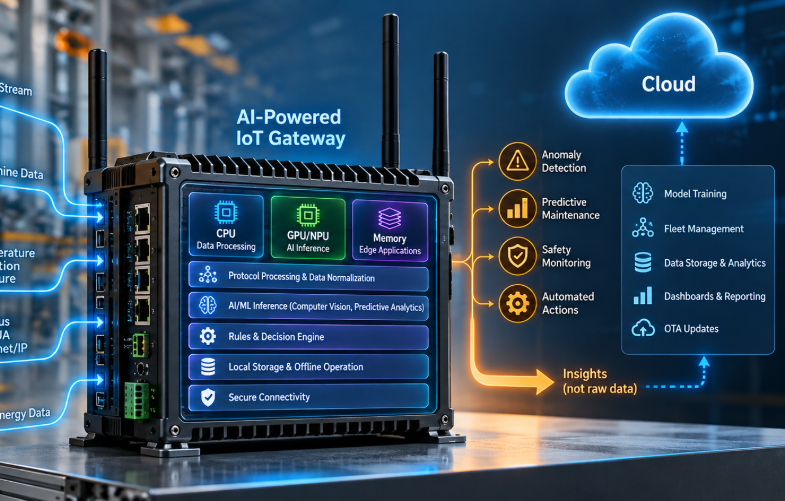
Modern edge processors include CPUs, GPUs, NPUs, and dedicated AI accelerators capable of running workloads that previously required server infrastructure.
NVIDIA's Jetson Orin Nano platform, for example, is designed for edge AI workloads including vision models, robotics, multimodal AI, and generative AI. NVIDIA lists up to 67 INT8 TOPS for its current Orin Nano Super developer platform.
Intel's OpenVINO ecosystem similarly supports inference across CPUs, GPUs, and NPUs, allowing developers to deploy optimized AI models on edge hardware.
That means the gateway can perform far more than protocol conversion.
IoT data volumes are growing
Sending every measurement, image, vibration waveform, and video stream to the cloud can become inefficient.
Edge processing allows the gateway to transform:
Raw data → information → event → action
before transmission.
Instead of sending ten thousand readings, the gateway might send:
“Motor vibration profile exceeded the learned operating pattern at 14:32.”
The cloud receives a higher-value event instead of an endless stream of raw telemetry.
Some decisions cannot wait for the cloud
Cloud round trips introduce network dependency.
Even a well-designed cloud architecture can be affected by:
- WAN latency
- Temporary outages
- Congested networks
- Cellular coverage problems
- Cloud service disruptions
In many industrial, automotive, healthcare, robotics, and safety applications, the system still needs to work locally.
Microsoft's Azure IoT Edge architecture explicitly supports local analytics and extended offline operation. After synchronization, edge modules and downstream devices can continue functioning without active cloud connectivity while messages are stored for later delivery.
AI models are becoming easier to deploy outside the cloud
The tooling around edge inference has improved significantly.
AWS IoT Greengrass, for example, supports local machine learning inference using cloud-trained models and allows inference, runtime, and model components to be deployed to edge devices.
This separation is important.
Training can still happen centrally.
Inference can happen locally.
That gives architects a practical hybrid model.
How an AI-Powered IoT Gateway Works
A useful mental model is to think of the gateway as six layers.
1. Device connectivity
The gateway first communicates with physical devices.
Typical interfaces may include:
- Ethernet
- Wi-Fi
- BLE
- Zigbee
- LoRaWAN
- RS-232
- RS-485
- CAN
- USB
- OPC UA
- Modbus
Its first responsibility is still connectivity.
2. Protocol normalization
Industrial environments rarely use one protocol.
The gateway may convert several device-specific data formats into a common internal representation.
For example:
Modbus + BLE + CAN → normalized telemetry
This makes downstream processing easier.
3. Local data processing
Before AI is involved, the gateway may perform:
- Filtering
- Noise removal
- Sampling
- Aggregation
- Unit conversion
- Time synchronization
- Data validation
Cleaning data before inference can be just as important as the AI model itself.
4. AI inference
The processed data enters one or more local models.
Examples include:
Camera → object detection → person detected
Vibration sensor → anomaly model → abnormal bearing pattern
Microphone → acoustic model → equipment fault signature
Temperature + pressure + vibration → predictive model → probable failure risk
The gateway does not necessarily train the model.
Its primary role is usually inference, meaning it runs a previously trained model against new data.
5. Decision and action
The gateway can then apply rules or application logic.
For example:
AI confidence > threshold → stop machine
or:
Occupancy detected + CO2 high → increase ventilation
or:
Defect detected → reject product
The decision remains local.
6. Cloud synchronization
The cloud still remains valuable for:
- Long-term storage
- Model training
- Fleet management
- Dashboards
- Cross-site analytics
- User management
- Historical reporting
- OTA updates
- Model deployment
AWS describes this architecture as allowing devices to analyze data locally, react autonomously, and selectively communicate with cloud services.
The better design is usually not edge versus cloud.
It is edge plus cloud.
Tools and Stack Options
There is no single standard technology stack for an AI IoT gateway.
The right choice depends heavily on workload.
NVIDIA Jetson
Jetson is commonly considered when the gateway needs substantial GPU acceleration.
Typical workloads include:
- Computer vision
- Multiple camera feeds
- Object detection
- Robotics
- Vision-language models
- Deep-learning inference
JetPack provides NVIDIA's edge software environment, including components such as CUDA, cuDNN, and TensorRT.
The trade-off is that GPU-based platforms may require more power and thermal planning than lightweight gateways.
Intel plus OpenVINO
Intel-based systems can be useful where x86 compatibility matters or existing industrial software already runs on Intel hardware.
OpenVINO supports AI inference across Intel CPUs, GPUs, and NPUs and provides a common runtime for deploying models across those targets.
This can work well for industrial PCs and gateway systems that need both conventional software workloads and AI inference.
ARM gateways
Lower-power ARM systems can work well for lighter models.
Potential workloads include:
- Sensor anomaly detection
- Small TensorFlow Lite models
- Audio classification
- Environmental monitoring
- Simple vision models
The advantage is lower power and cost.
The limitation is available compute.
AI accelerators
Dedicated NPUs and inference accelerators are becoming increasingly important.
Instead of running every AI operation on the CPU, workloads can be moved to hardware optimized specifically for neural-network inference.
This can improve:
- Latency
- Throughput
- Energy efficiency
For production gateways, performance-per-watt can matter more than peak benchmark performance.
Best Practices for Designing AI-Powered IoT Gateways
Start with the decision, not the model
Do not begin with:
“Which AI model should we deploy?”
Begin with:
“Which decision must happen locally?”
Examples:
- Stop a machine
- Detect an unsafe zone
- Identify a defect
- Predict abnormal operation
- Filter irrelevant data
- Recognize occupancy
The decision determines the latency, model, sensors, and compute requirements.
Define acceptable inference latency
A gateway detecting a manufacturing defect may need a response within milliseconds.
A gateway estimating equipment deterioration may only need a result every few minutes.
Those are very different requirements.
Benchmark the full pipeline:
Sensor → preprocessing → inference → rule → actuator
not just model inference.
Design for offline operation
A production gateway should clearly define what happens when cloud connectivity disappears.
Ask:
- Does AI inference continue?
- Can commands still execute?
- How much data can be buffered?
- What happens when storage becomes full?
- How is data synchronized after reconnection?
Microsoft's IoT Edge runtime, for example, supports local message storage and synchronization after connectivity returns.
Separate AI models from application logic
Avoid tightly coupling a model to the entire gateway application.
A cleaner architecture separates:
Device drivers
Preprocessing
Inference runtime
Model
Business rules
Cloud communication
That makes model replacement far easier.
Plan model updates from day one
AI models change.
Thresholds change.
Training data changes.
The production architecture should support controlled deployment of:
- New models
- Previous models
- Configuration updates
- Rollbacks
Treat model lifecycle management much like software lifecycle management.
Common Pitfalls
The first mistake is choosing hardware too early.
A team sees an AI accelerator and designs around it before measuring actual workload requirements.
Prototype the inference pipeline first.
Then size the gateway.
The second mistake is assuming edge AI removes the cloud.
Usually it does not.
The cloud remains useful for fleet-level visibility and model lifecycle management.
The third mistake is sending everything to the cloud anyway.
If an edge AI gateway performs inference but still uploads every raw frame or sensor sample continuously, much of the architectural benefit disappears.
The fourth mistake is ignoring observability.
Production teams need to know:
- Is the gateway online?
- Is the AI process running?
- Which model version is active?
- What is inference latency?
- Is CPU or accelerator utilization abnormal?
- Is storage filling?
- When was the last successful cloud synchronization?
Monitoring the AI workload is as important as monitoring the device.
Performance, Cost, and Security Considerations
Performance
Do not evaluate gateway performance using processor specifications alone.
Measure the actual workload.
For computer vision, evaluate:
- Frames per second
- Resolution
- Number of cameras
- Preprocessing time
- Model size
- Inference latency
For sensor AI, evaluate:
- Sampling rate
- Window size
- Model complexity
- Number of sensors
- Event frequency
A theoretically powerful device can still perform poorly if the complete pipeline is inefficient.
Cost
AI gateways are usually more expensive than simple protocol gateways.
But hardware cost is only one part of the equation.
Local intelligence may reduce:
- Cloud compute
- Bandwidth consumption
- Data storage
- Network dependency
- Manual inspection
- Site visits
AWS specifically positions local inference as a way to reduce latency and avoid unnecessary transfer of data to the cloud.
The correct comparison is therefore not:
Gateway A costs $X and Gateway B costs $Y.
It is:
What is the total operating cost of the architecture over the deployment lifecycle?
Security
Moving intelligence to the edge creates additional security responsibilities.
The gateway may contain:
- Credentials
- AI models
- Business logic
- Local databases
- Device certificates
- Network access
- Sensitive sensor data
Security therefore needs multiple layers:
- Secure boot
- Signed firmware
- Encrypted storage
- TLS communication
- Device certificates
- Role-based access
- Network segmentation
- Controlled OTA updates
- Model integrity verification
- Audit logging
An edge AI gateway is no longer just networking hardware.
It is a computing platform.
Secure it like one.
Real-World Use Case: Predictive Maintenance
Consider an industrial plant with rotating machinery.
Traditional architecture
Vibration sensors collect measurements.
The gateway forwards readings to the cloud.
Cloud analytics identifies unusual patterns.
An alert is generated.
This works, but every decision depends on connectivity and cloud processing.
AI gateway architecture
The gateway continuously receives vibration data.
A local model analyzes short windows of sensor information.
Most readings are discarded after processing.
Only abnormal patterns and summary statistics are uploaded.
If the system detects a potentially dangerous pattern, the gateway can immediately notify the local control system.
The cloud still performs:
- Historical analysis
- Model retraining
- Fleet comparison
- Dashboarding
But time-sensitive detection happens locally.
This split illustrates the broader principle behind intelligent gateways:
The edge handles immediate intelligence. The cloud handles broader intelligence.
AI Gateway vs Traditional IoT Gateway
A traditional gateway primarily moves and transforms data.
An intelligent gateway interprets it.
A conventional device might perform:
Sensor → Gateway → Cloud → Analytics → Decision
An AI gateway can perform:
Sensor → Gateway → AI inference → Local decision
and then:
Relevant result → Cloud
That architectural difference can improve latency, resilience, and bandwidth efficiency.
However, not every deployment needs AI at the gateway.
If telemetry is lightweight, latency is unimportant, connectivity is stable, and cloud processing is inexpensive, a conventional gateway may remain the better option.
Edge AI should solve an architecture problem, not become an architecture requirement simply because AI hardware is available.
When Should You Use an AI-Powered IoT Gateway?
Consider local AI when one or more of these conditions exist:
- Decisions must happen in real time.
- Connectivity is unreliable.
- Devices generate large data volumes.
- Video or audio processing is involved.
- Raw data should remain on-site.
- Cloud bandwidth costs are significant.
- Equipment must keep operating during network outages.
- Local automation must continue independently.
- Sending all data centrally creates unnecessary processing.
A particularly strong case exists when several conditions appear together.
For example:
High-resolution cameras + low latency + limited bandwidth
is a classic edge AI scenario.
A temperature sensor reporting once every ten minutes probably is not.
FAQs
What is an AI-powered IoT gateway?
It is an IoT gateway capable of running local AI or machine learning inference in addition to device connectivity, protocol translation, and cloud communication.
Why are AI models moving to IoT gateways?
Running inference near the data source can reduce latency, decrease bandwidth use, support offline operation, and enable immediate local actions.
Can IoT gateways run machine learning models?
Yes. Modern gateway hardware can run frameworks and runtimes such as TensorFlow Lite, OpenVINO, TensorRT, and custom inference engines. AWS IoT Greengrass also supports deployment of machine learning inference components to compatible edge devices.
Does edge AI replace cloud computing?
Usually not.
The strongest architectures combine both. Edge systems handle time-sensitive decisions, while the cloud handles centralized management, large-scale analytics, historical storage, and model training.
Are AI gateways more secure than cloud AI?
Not automatically.
Keeping sensitive raw data local can reduce unnecessary transmission, but the gateway itself becomes a valuable computing asset that must be protected.
What hardware does an AI gateway need?
That depends on the workload. Light sensor models may run on ARM CPUs, while advanced vision workloads may require GPUs or NPUs.
Can AI gateways work without internet access?
Yes, if the software architecture is designed for offline operation. Platforms such as Azure IoT Edge support local processing and message storage while disconnected.
What industries use edge AI gateways?
Common applications include manufacturing, energy, smart buildings, healthcare devices, transportation, retail, agriculture, robotics, and smart infrastructure.
What is the difference between edge computing and edge AI?
Edge computing means processing data near where it is produced.
Edge AI is a subset of edge computing where AI or machine learning models perform inference locally.
How do you choose an AI IoT gateway?
Start with workload requirements rather than hardware specifications. Define the sensors, model type, expected latency, power limits, connectivity, environmental conditions, security requirements, and device-management strategy before selecting the platform.
The next generation of IoT gateways will not just move data. They will understand it, decide what matters, and act before the cloud is involved

Conclusion
AI-powered IoT gateways represent a fundamental shift in connected-product architecture. The gateway is moving beyond protocol conversion and cloud connectivity to become a local intelligence layer capable of processing data, running AI inference, making decisions, and triggering actions close to where events happen.
That does not mean every IoT system needs AI at the edge. For simple telemetry, stable connectivity, and non-critical workloads, traditional gateways and cloud processing may still be the most practical choice. But when latency, bandwidth, privacy, resilience, or real-time automation matter, moving intelligence closer to the device can significantly change how the system operates.
The key architecture question is therefore no longer simply “edge or cloud?” It is “which decisions belong on the device, which belong on the gateway, and which belong in the cloud?” Getting that split right is what turns edge AI from an impressive technology demonstration into a reliable production IoT architecture.
Building a connected product that needs faster decisions, lower cloud dependency, or intelligence at the edge?
Infolitz helps teams design the right split between devices, AI-powered gateways, and cloud platforms, from embedded software and edge AI to IoT backends and production deployment.
Talk to Infolitz about your IoT and Edge AI architecture.


